Red Flags I Look For in a Codebase and Team
By Tom Lang on September 16, 2026
I'm Tom Lang — I've built and scaled engineering organizations for three decades, through multiple acquisitions, and I work as a fractional and interim CTO for growth-stage companies, with particular depth in regulated and integration-heavy environments.
When I run a Diagnostic, I'm not just looking for bad code. Code can be refactored — that's the easy part. What I'm actually hunting for is systemic organizational rot: the behaviors and structural flaws that will eventually paralyze the business, no matter how clean the syntax looks. It's why a diagnostic is 70% people and process, not code review.
Here's my actual priority list — the red flags I scan for first, the tell for each, and what it predicts. Then the two that matter most: the single most dangerous flag, and the one founders are proudest of that scares me the most.
The red-flag hit list
1. The hero developer — the single point of failure. The tell: one engineer's name is on every critical pull request. Deployments only happen when they're online. They complain about being overworked but actively refuse to delegate, block others from touching "their" code, and say "it's just faster if I do it myself." Why it matters: it predicts complete operational paralysis, and it masks terrible onboarding, missing documentation, and a quietly toxic culture. If that person gets poached or burns out, your company effectively stops functioning. A hero isn't an asset; it's a bus-factor of one.
2. The "everything is P0" roadmap. The tell: Jira is a graveyard of half-finished epics. The sprint board changes three times a week off the latest customer call. Product never says "no" to the CEO, and engineering gets treated like a short-order kitchen. Why it matters: it predicts zero actual velocity. When developers context-switch constantly, nothing ever reaches 100% done. You're paying for constant motion and getting zero forward momentum — not the same thing, though they look identical on a status update.
3. Resume-driven architecture. The tell: a startup with $2M ARR and 5,000 users running a sprawling Kubernetes microservices mesh, Kafka event streaming, and three different NoSQL databases. Why it matters: the engineers built a system to get themselves hired at Google, not to serve your business. That hyper-complexity will crush a small team, bloat your cloud bill, and make every feature painfully slow to ship. Complexity you didn't need is complexity you now pay to operate forever.
4. Fear of the codebase. The tell: the team manually tests everything for days before a release, and there's a specific legacy module — usually billing or core logic — that everyone warns new hires "not to touch or breathe on." Why it matters: it means you have zero automated safety nets. When developers are afraid of their own system, innovation stops — they build elaborate, hacky workarounds just to avoid touching the scary part, which compounds the very debt that made it scary.
5. Blindness to failure — customer-driven monitoring. The tell: the engineering team finds out the site is down because the CEO gets an angry text from a customer, or Support gets flooded with tickets. Why it matters: it proves a total lack of observability. If you don't know the system is broken before your customers do, your time-to-resolution is dictated by luck, not engineering. Fixing this is most of what reliability without an SRE team is about.
6. The missing staging environment. The tell: engineers merge and push straight to production, or "staging" has dummy data that hasn't been updated since 2023 and looks nothing like the real world. Why it matters: it predicts catastrophic data loss. Testing in production is survivable for a minor UI tweak; it's a death sentence for a database migration or a payment gateway.
The two that matter most
Of all of them, two sit at the extremes — and they're the ones I really watch for.
The most dangerous: the adversarial culture. The tell: Engineering and Product treat each other like enemy nations. Engineering says, "Product writes garbage specs." Product says, "Engineering is lazy and slow." The reality: this is the true "walk away or fix immediately" signal. I can fix bad architecture in a few months. I cannot fix a product if the people building it refuse to collaborate. When trust between those two functions is gone, the company is dying — even if the runway still looks fine on the spreadsheet. If I find this, I pause all code development and fix the relationship first, because nothing technical I do will hold until I do.
The most deceptive: "we ship super fast!" The tell — what the founder brags about: "Our team is amazing. They can crank out a massive new feature in a weekend. Our velocity is incredible." The reality — what terrifies me: they're shipping that fast because they're omitting the foundation — no tests, no code review, no thought for edge cases. This is the velocity illusion, the same velocity paradox I flagged as snake oil: high-interest technical-debt payday loans, taken out to buy the appearance of speed. Within 12 to 18 months the interest comes due — bugs consume 90% of the team's time and the platform grinds to a halt. The founders who brag about weekend features are usually 12 months from calling me in a panic.
The pattern
Notice it: almost none of these are really about code. The hero developer, the P0 chaos, the adversarial culture, the bragging about speed — the reddest flags are human and organizational, and the code is just where the symptom shows up. That's the whole reason I look at the people before the repo.
If you read this list and recognized your own company in two or three of them, that's not a crisis — it's a diagnosis waiting to happen, and every one of these is fixable if you catch it early. Finding exactly which ones you have, and what order to fix them in, is what the Diagnostic is for. Book a call and we'll take an honest look.
Related reading
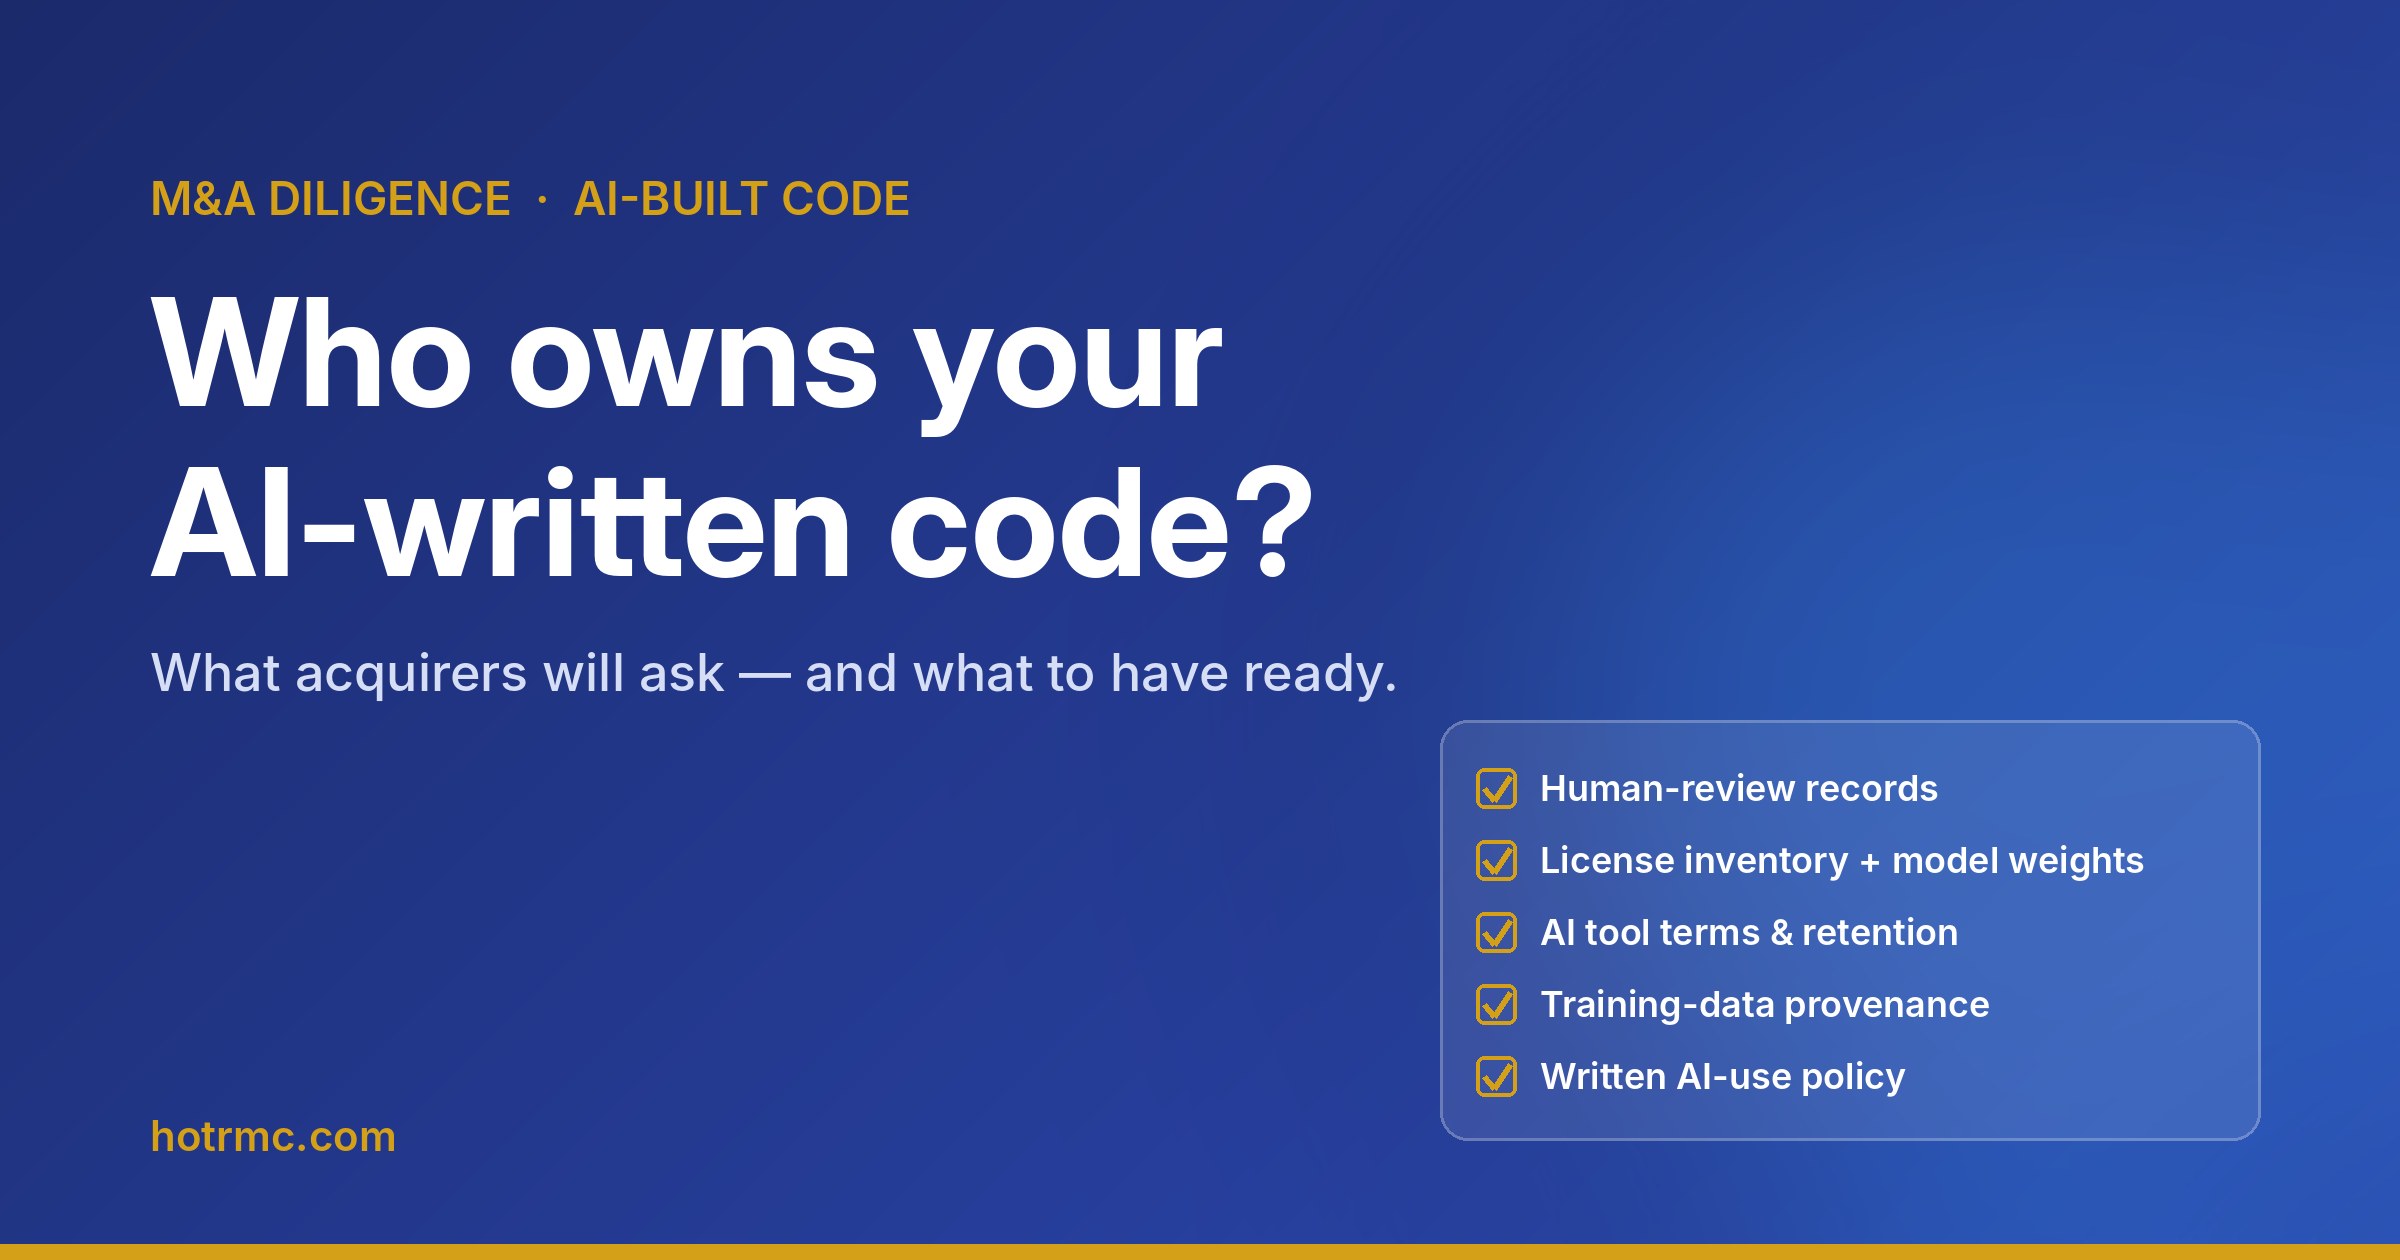
Who Owns Your AI-Written Code? What Acquirers Will Ask
By Tom Lang on November 2, 2026
Buyers have started asking a question most engineering teams can't answer yet: who actually owns your AI-written code? Ownership isn't automatic, and diligence now asks for records of human review, a license inventory that includes model weights, your AI tools' data-retention terms, and governance evidence. Here's the five-part checklist to have ready before the data room opens — and why it's cheap to prepare now and brutal to reconstruct later.
Read more
How Investors Spot Technical Risk in a Portfolio Company — Before It's Expensive
By Tom Lang on October 5, 2026
You don't need to read code to spot a portfolio company headed for an expensive technical problem. The signals are all outside the codebase — and by the time they show up in the numbers, the problem is already costly. Here's how to read technical risk early, including the AI risk most people aren't reading yet — without commissioning a full audit.
Read more
The 5 Signs Your Engineering Is Quietly Burning Your Runway
By Tom Lang on October 5, 2026
Engineering rarely fails loudly. There's usually no single disaster — just a slow leak that looks like 'busy' right up until it looks like a crisis. Here are five signs, in business terms, that your engineering is costing you more than it should — and what each one actually signals. None of them are really code problems; they're judgment problems.
Read more